RLVR as prompt augmentation reinforces both correct and incorrect reasoning
An outcome reward cannot tell reasoning apart from any other scaffold that reaches the right answer. RLVR up-weights a chain of thought by how much it raises the chance of a correct answer, valid or not.
The claim
For a chain of thought c on a prompt x, the optimal RLVR policy satisfies log π*(c | x) / πbase(c | x) = log P(correct | x, c) / P(correct | x). The per-token value differences telescope, so a chain of thought is reinforced exactly when it raises the probability of a correct final answer relative to the prompt alone. The objective is indifferent to every other property of the chain of thought, including its validity, semantics and faithfulness. RLVR learns prompt augmentations conditioned on success.
Two testable predictions
- In a domain where traces can be verified formally (maze navigation with A* traces), RLVR should raise accuracy without raising trace validity.
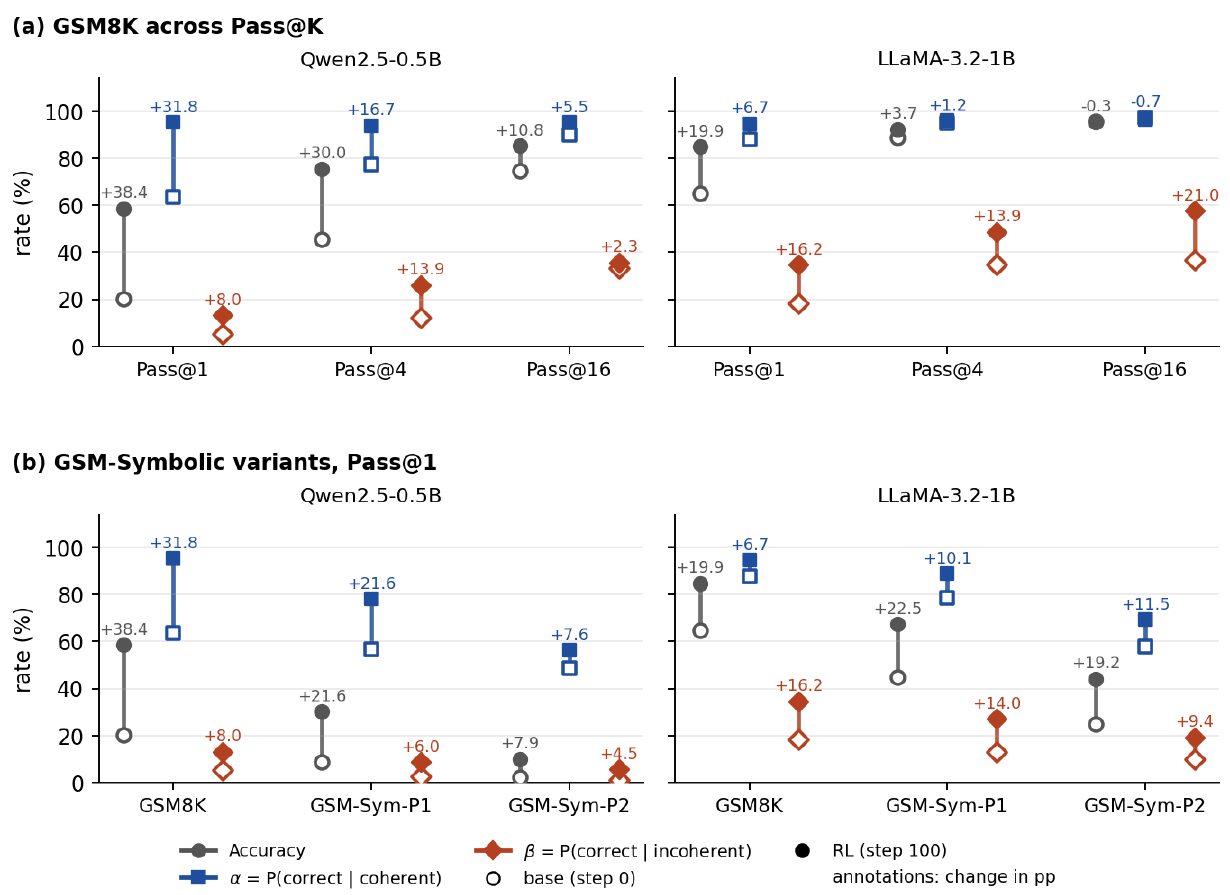
- In math, where validity cannot be checked at scale, RLVR should raise the rate of correct answers reached through incoherent reasoning, not only through coherent reasoning.
To test the second prediction, we measure trace coherence by identifying errors in each reasoning step with a first-order-logic framework, and compute α = P(correct | coherent trace) and β = P(correct | incoherent trace) before and after RLVR on GSM8K and the GSM-Symbolic variants P1 and P2.
What it means
Rising accuracy after RLVR is not evidence that the model learned to reason correctly. The objective rewards any chain of thought that makes the right answer more likely, and incoherent ones are reinforced along with coherent ones. Claims that RLVR implicitly incentivizes correct reasoning need a measure of the reasoning itself, not only of the final answer.
This paper is under double-blind review at ICLR 2027. The PDF is the submitted version.