RL post-training, and
evaluating LLMs to their limits.

I am a third-year PhD student at Arizona State University who takes a critical look at what RL post-training really changes in LLMs, and evaluates them to their reasoning limits. I am advised by Subbarao Kambhampati in the Yochan Lab.
Portrait of Soumya Rani Samineni
My profile
ResumeStatement
My publications
Google Scholar
My channel
RL4LLMs
To collaborate
ssamine4@asu.edu
To build
GitHubKaggle
To connect
soumya-rani
To stay in touch
@soumya_samineni

I am looking for research internships for summer 2027, and I am open to research collaborations.
How I work

A critical outlook and skeptical evaluation

I take a critical look at RL post-training and enjoy evaluation work that tests LLMs to their limits.

A critical look at RL post-training

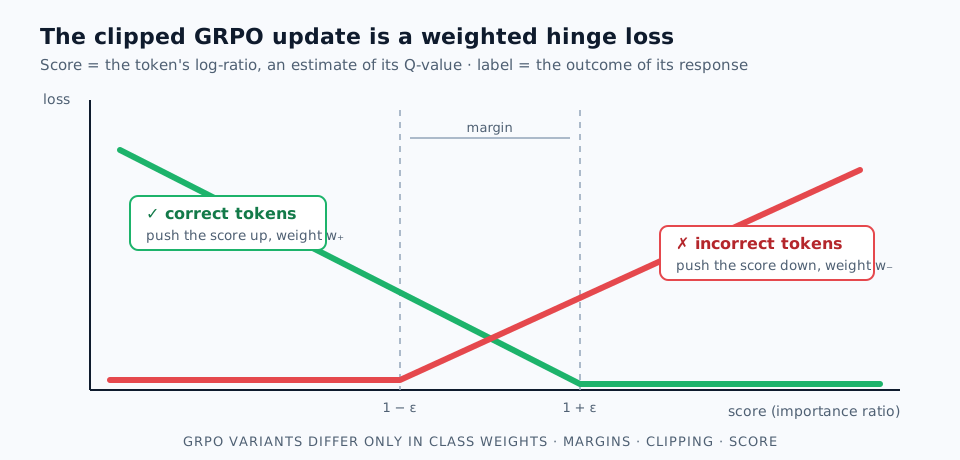
What RL with verifiable rewards changes in a model, and what it only appears to change. Theory of the update, checked with post-training runs in verl.

Skeptical evaluation of reasoning

Measuring the reasoning, not only the final answer. Trace coherence, trace validity, and correct answers reached through incoherent reasoning.

Multi-turn and agentic RL

Credit assignment across turns as well as tokens, and evaluation of reasoning in non-ergodic worlds, where one bad outcome can end a trajectory.

Publications

Papers and patents

  1. 2026

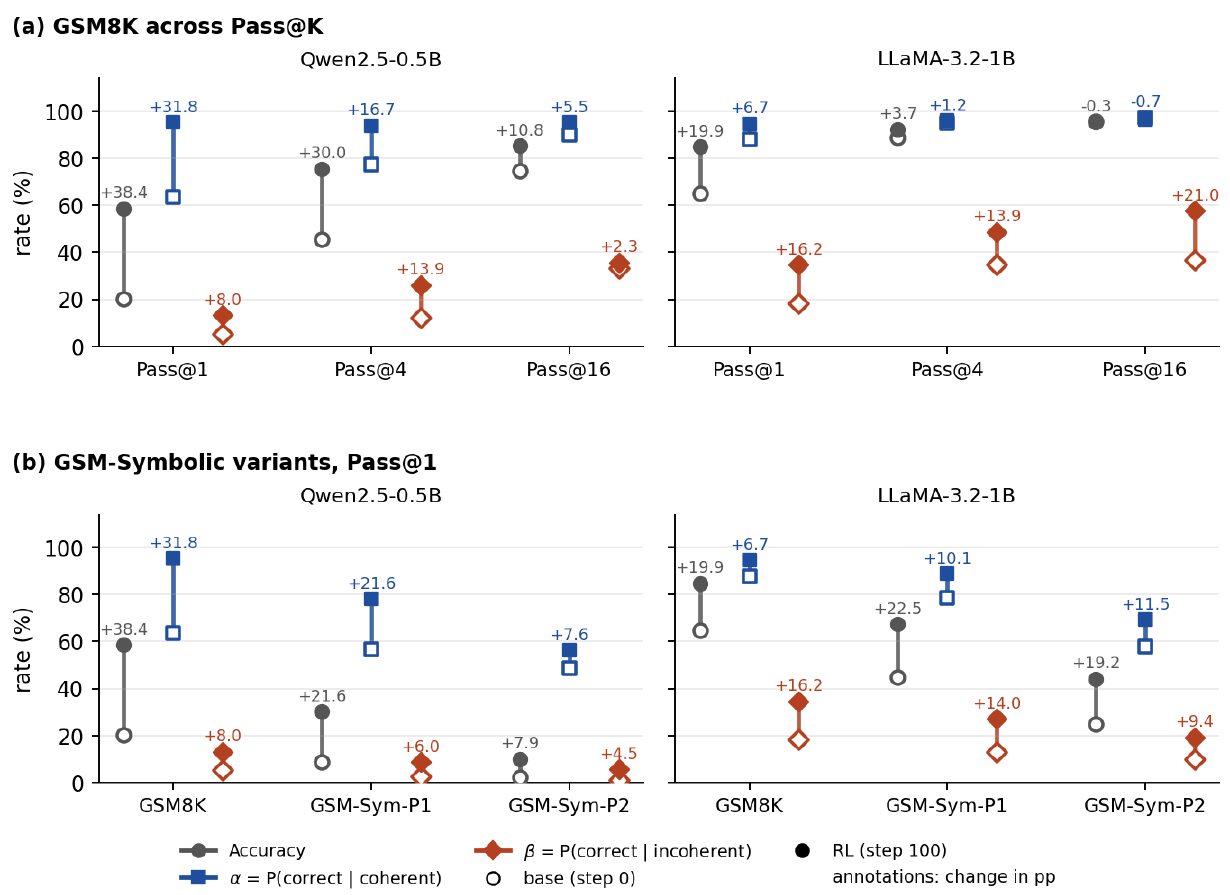
    RLVR as Prompt Augmentation Reinforces Both Correct and Incorrect Reasoning to the Correct Answer

    Under review at ICLR 2027

    Paper page PDF

  2. 2026

    Position: Stop Anthropomorphizing Intermediate Tokens as Reasoning/Thinking Traces!

    S. Kambhampati, K. Valmeekam, S. Bhambri, V. Palod, L. Saldyt, K. Stechly, S. R. Samineni, D. Kalwar, U. Biswas

    ICML 2026 · Position paper

    arXiv

  3. 2025

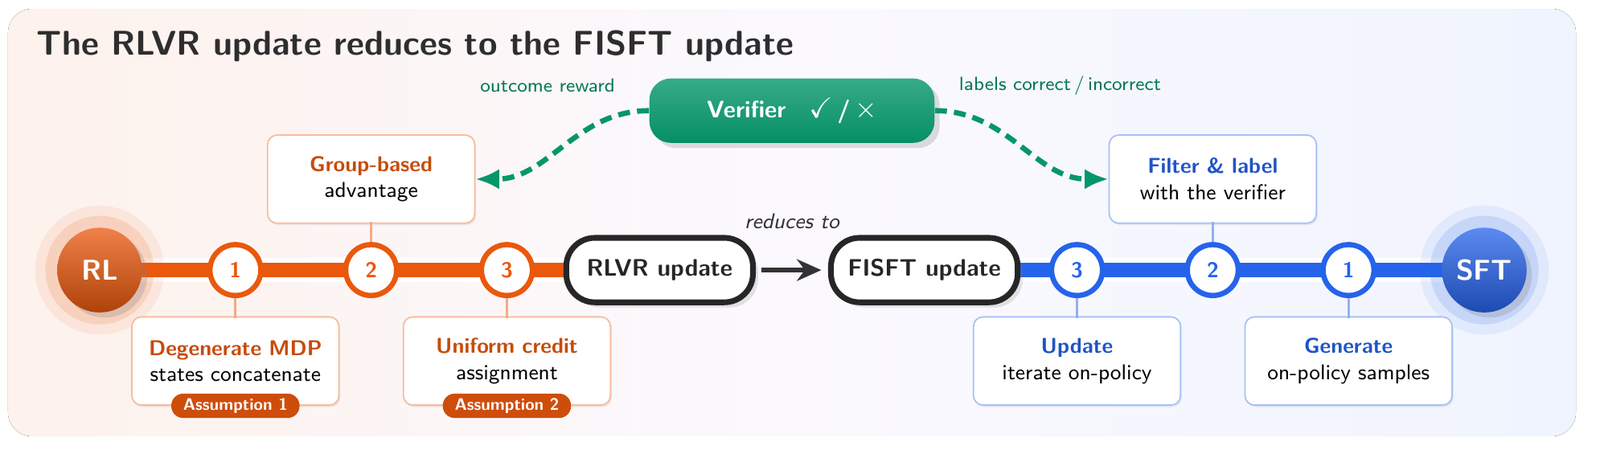
    RL in Name Only? Analyzing the Structural Assumptions in RL post-training for LLMs

    S. R. Samineni*, D. Kalwar*, K. Valmeekam, K. Stechly, S. Kambhampati

    NeurIPS 2025 · Workshop on Bridging Language, Agent, and World Models (LAW)

    Paper page arXiv

  4. 2025

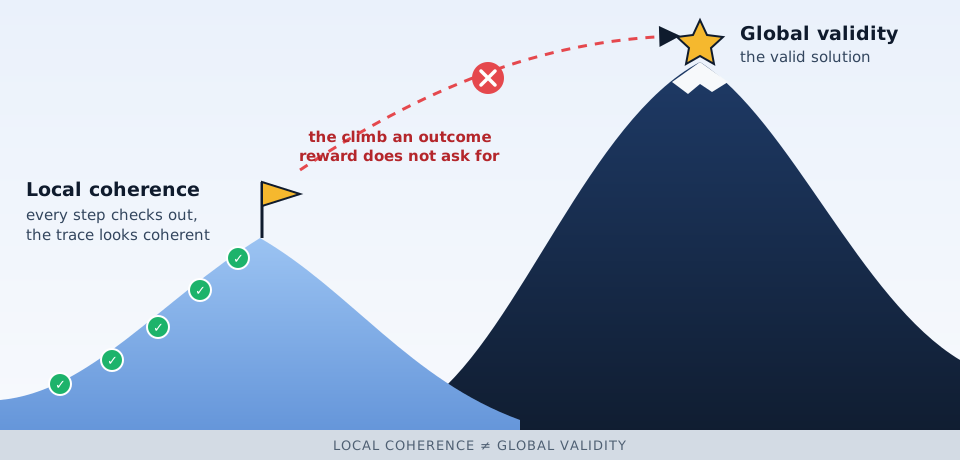
    Local Coherence or Global Validity? Investigating RLVR Traces in Math Domains

    S. R. Samineni, D. Kalwar, V. Gangal, S. Bhambri, S. Kambhampati

    NeurIPS 2025 · Workshop on Mathematical Reasoning and AI

    Poster page arXiv

  5. 2024

    System and Method for Intelligent Scheduling of Manufacturing Jobs

    D. Birru, A. Deodhar, A. Chaudhary, S. R. Samineni

    US patent application US20240319718A1

    Patent

  6. 2022

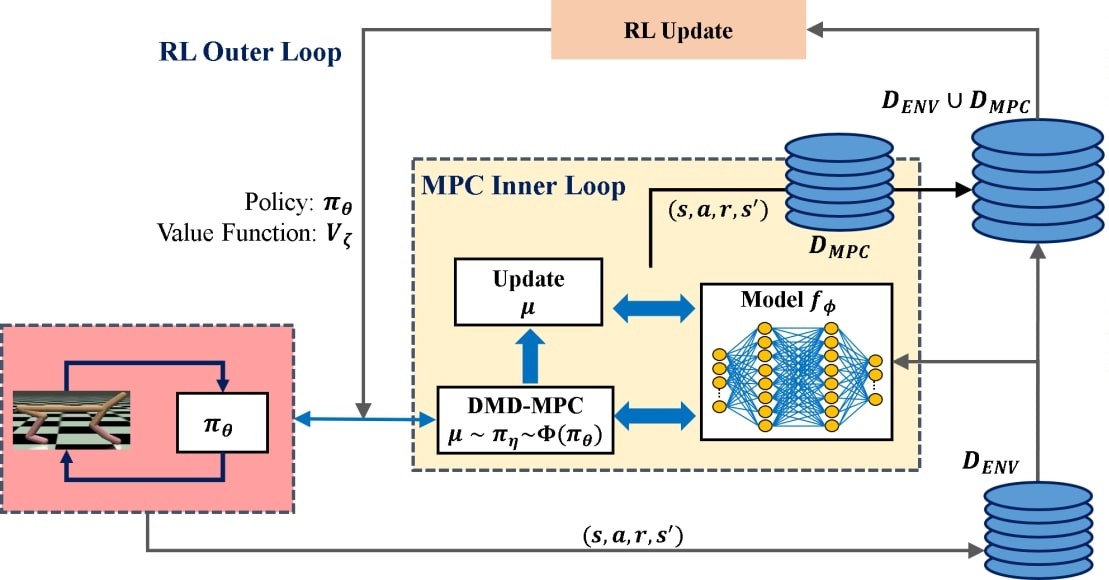
    Dynamic Mirror Descent based Model Predictive Control for Accelerating Robot Learning

    S. R. Samineni*, U. Mishra*, P. Goel, C. Kunjeti, H. Lodha, A. Singh, A. Sagi, S. Bhatnagar, S. Kolathaya

    ICRA 2022 · also NeurIPS 2021 Deep RL and Offline RL workshops

    Project page arXiv Video

  7. 2021

    Policy Search using Dynamic Mirror Descent MPC for Model Free Off Policy RL

    S. R. Samineni

    M.Tech thesis, Indian Institute of Science

    arXiv Code

100+ citations on Google Scholar See the live list on Google Scholar →

Relevant projects

Other projects from my PhD

Jan'25 – May'25 · with Prof. Dimitri Bertsekas

Inference-time scaling with rollouts

Rollouts at every decoding step, with an LLM as the base policy and a verifier, on Game of 24, as an alternative to Tree of Thoughts.

2024 – 2025

VLM-generated rewards for inverse RL

Whether rewards from GPT-4V and CLIP can tell a learned policy's behavior apart from expert demonstrations.

2024 – 2025

Multi-agent LLMs for logic-grid puzzles

Agents that process clues iteratively and refine their solutions together.

Presentations and videos

Talks and walkthroughs of my papers and of what RL post-training does to language models.

Path

From reinforced concrete to reinforcement learning

  1. Aug'24 – now

    Graduate Researcher, Yochan Lab, Arizona State University

    Ph.D. in Computer Science and Engineering with Prof. Subbarao Kambhampati, expected May 2029, GPA 4.0. Theory and experiments on RL post-training of LLMs, reasoning and planning, and evaluation of reasoning traces.

  2. Jul'23 – Aug'24

    Machine Learning Research Engineer, Quantiphi Analytics

    Built an RL scheduler for flexible job-shop manufacturing with graph attention networks (TensorFlow, GCP). Co-inventor on US patent application US20240319718A1.

  3. Feb'22 – Jul'22

    Research Fellow, Microsoft Research India

    Built the RL framework for a renewable-energy market, where the agent handled carbon arbitrage and profit maximization.

  4. Jul'21 – Feb'22

    Solution Leader, Brane Enterprises

    Built a quadruped locomotion controller in lightweight C++ for microcontrollers (CAN, UART, ROS), cutting control latency to microseconds from the milliseconds reported in the source paper.

  5. 2019 – 2021

    M.Tech, Indian Institute of Science

    Stochastic Systems and Stochastic Robotics Labs with Profs. Shalabh Bhatnagar and Shishir Kolathaya. DeMo RL, a model-based lookahead for off-policy RL, improved sample efficiency by 30% in simulation and 2× on a real arm and quadruped (ICRA 2022). Thesis graded A+.

  6. Jun'18 – Jul'19

    Assistant Executive Engineer, Roads and Buildings Department, Government of Telangana

  7. 2012 – 2016

    B.Tech, Civil Engineering, NIT Warangal

Recognition

Grants, ranks and certificates

Contact

Working on RL for LLMs? Let's talk.

I am open to research collaborations and to research internships for summer 2027.